 Shopify
 AWS Architecture
Netflix built Quasar, a tool that links proposed Java API changes to actual references in consumer repositories, enabling measurement of a library change’s blast radius.

Company blogs
Engineering and data science write-ups straight from the teams at 30 companies. Each one summarised in a line or two and sorted by subject. New posts are added every morning.
Reading the blogs of
Loading posts…
Netflix built Quasar, a tool that links proposed Java API changes to actual references in consumer repositories, enabling measurement of a library change’s blast radius.
Netflix created single‑tenant Titus, adding VM‑level isolation to its multi‑tenant Kubernetes‑based container platform for stronger tenant separation.

Netflix built an ontology‑driven observability system that generates an end‑to‑end knowledge graph, providing real‑time insight into billions of requests and logging events at Netflix scale.

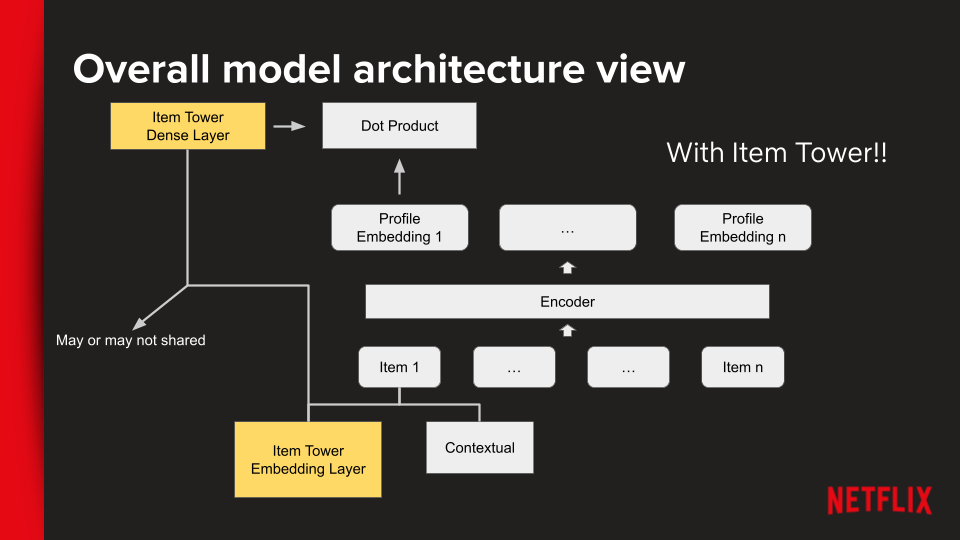
Netflix built a Foundation Model for personalization that learns from large‑scale user interaction and content data and shares its insights across downstream models.
Netflix open‑sourced DataJunction, a metric platform that consolidates scattered metrics, streamlines data workflows, and improves insight generation for experimentation.

Netflix described methods for measuring the value added by personalized recommendations, separating title appeal from personalization impact.

Netflix built a tiered storage system that moves older time‑series data from hot Kafka/Flink streams to native Cassandra cold reads, reducing storage costs while maintaining low‑latency access.

Netflix evolved its Ads Event pipeline into a centralized Ads Event Publisher that enriches ad telemetry and streams a unified feed to downstream consumers, improving consistency and handling encryption end‑to‑end.

Netflix expanded its internal Conductor workflow orchestration engine, rebuilding it to support higher scale after discontinuing the open‑source version, enhancing reliability and observability of micro‑service processes.

Netflix created a framework to run multiple Apache Spark experiments in parallel, automating monitoring and result tracking, which accelerated tuning of the member‑sessionizer pipeline at production scale.
